AI observability
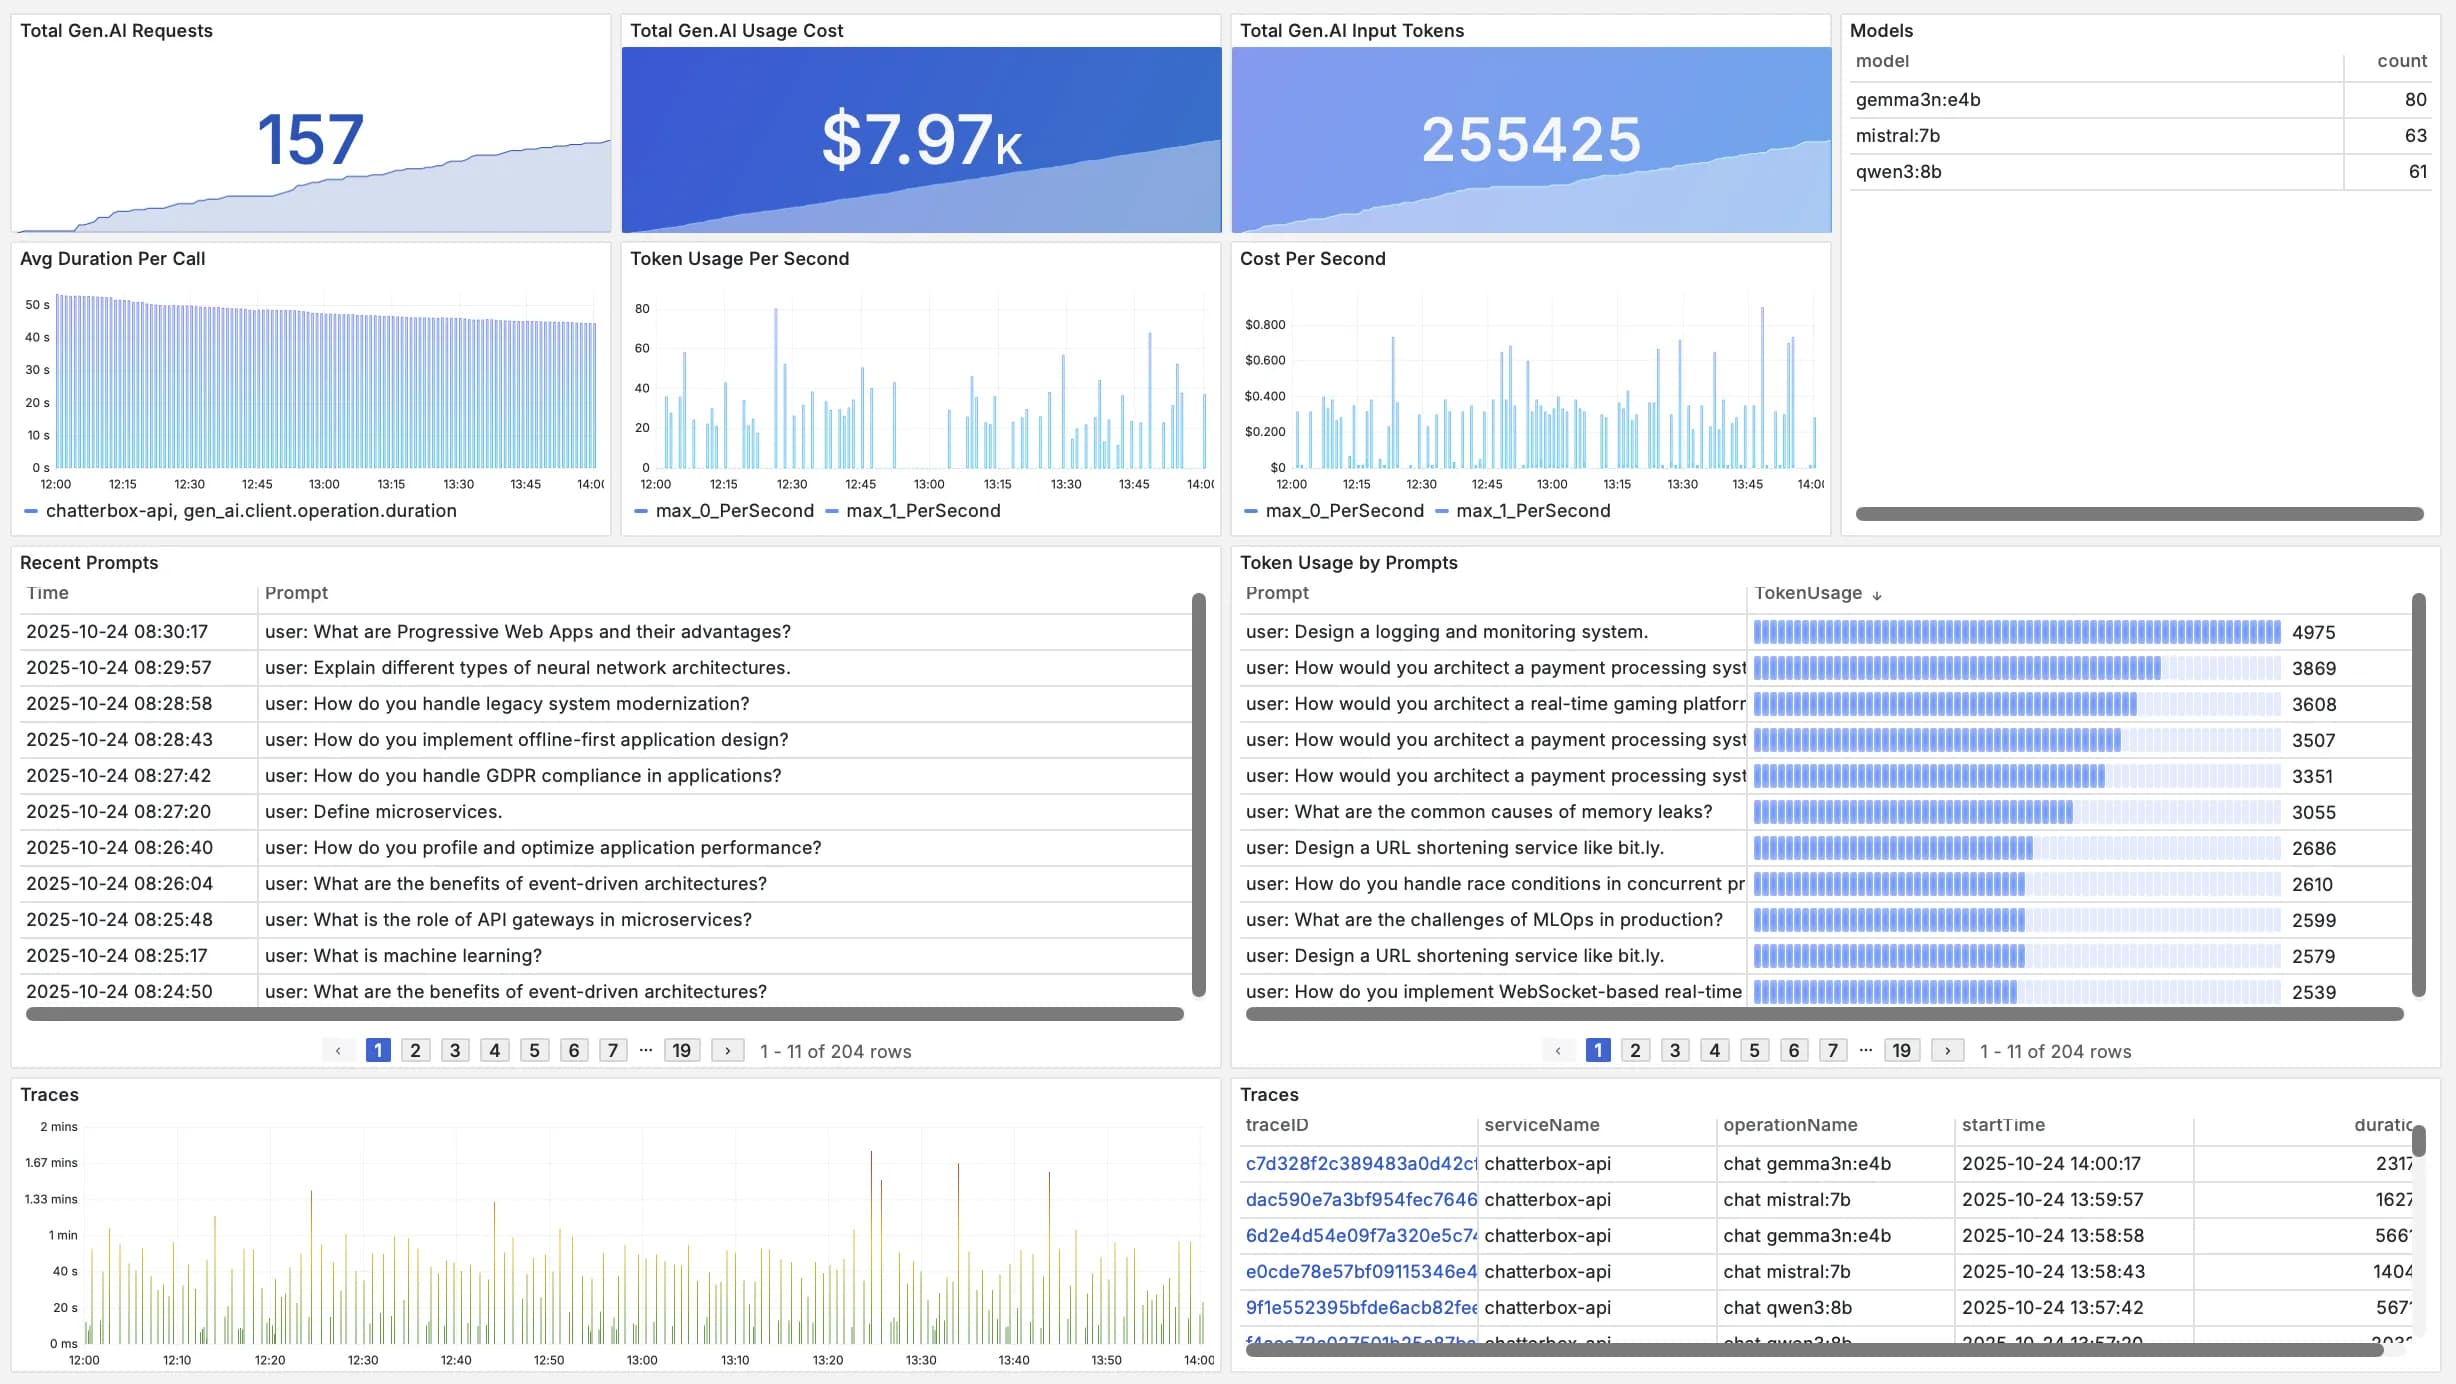
One trace from the HTTP request through every agent step, tool call, model call and database query. Tokens, cost, latency and quality for every model your product uses.
Trusted by industry leaders

See what your AI is actually doing
Scout follows OpenTelemetry's GenAI semantic conventions, so every LLM call and agent run lands in the same traces, metrics and logs as the rest of your stack.
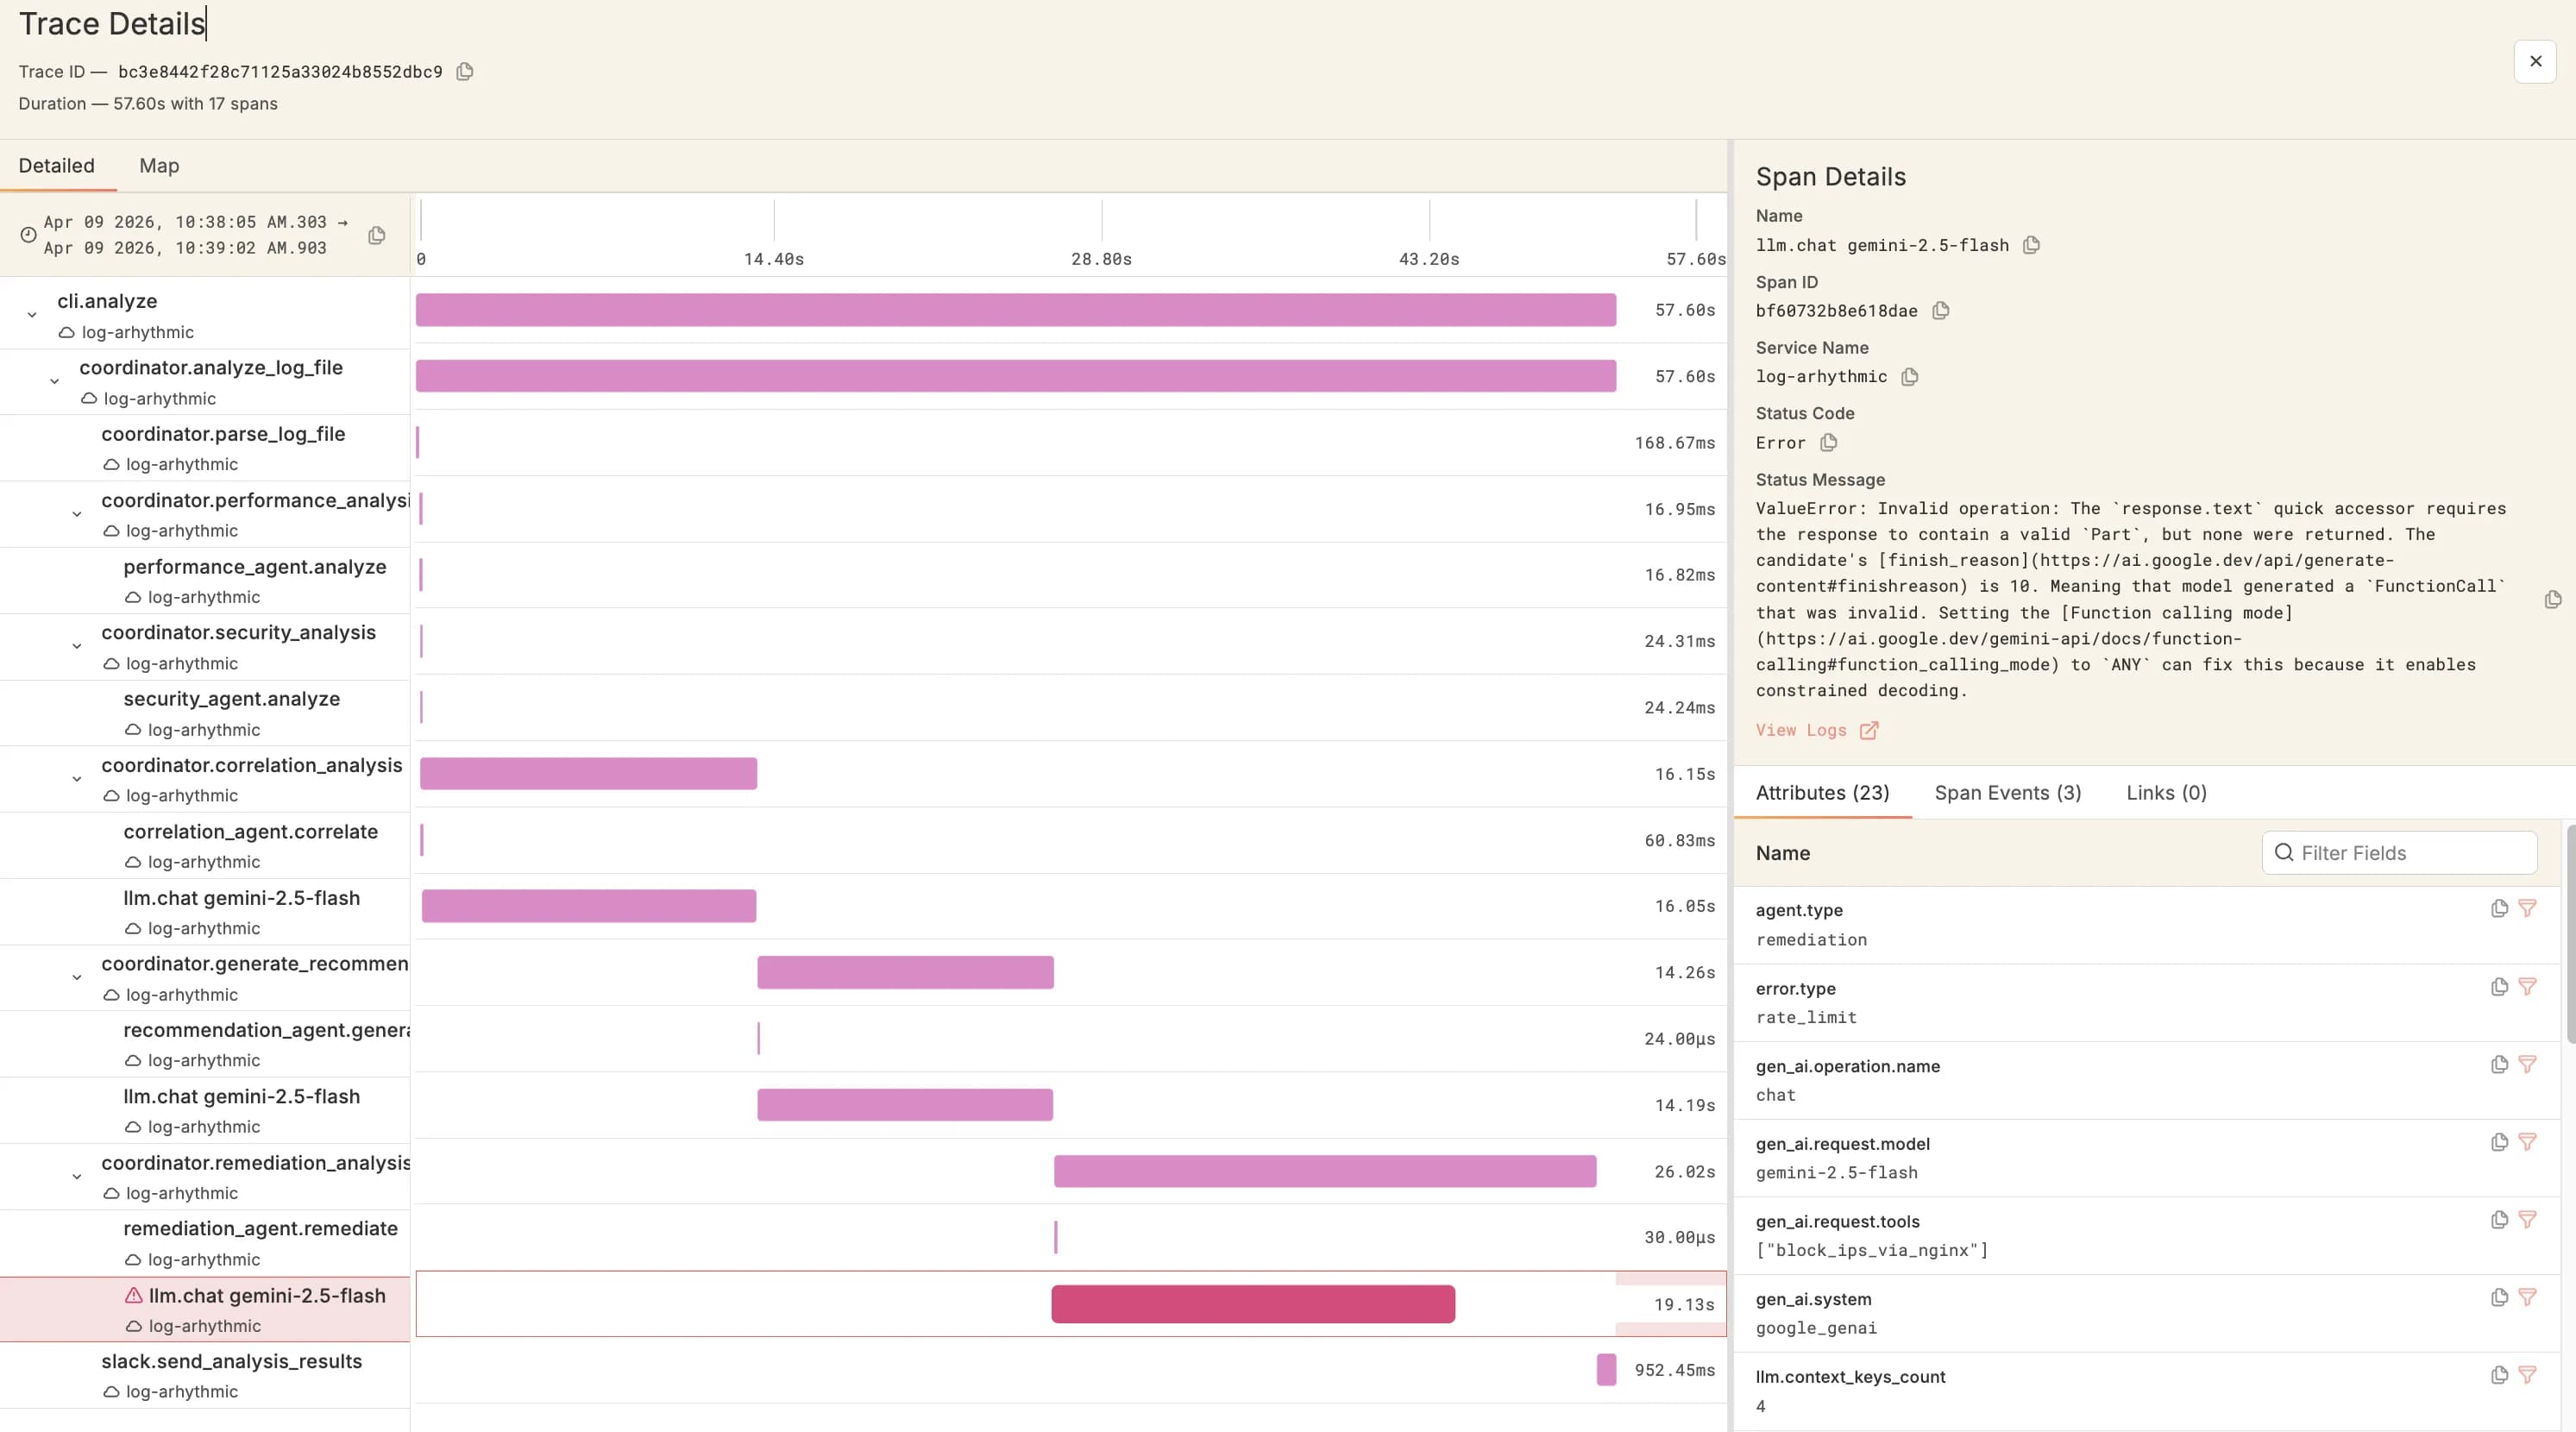
Every agent run is one waterfall: invoke_agent, chat, execute_tool and MCP tool spans stitched to the HTTP, queue and database spans around them, bound by a conversation ID.
- Tool and MCP call spans
- Multi-agent handoffs
- Conversation ID filter
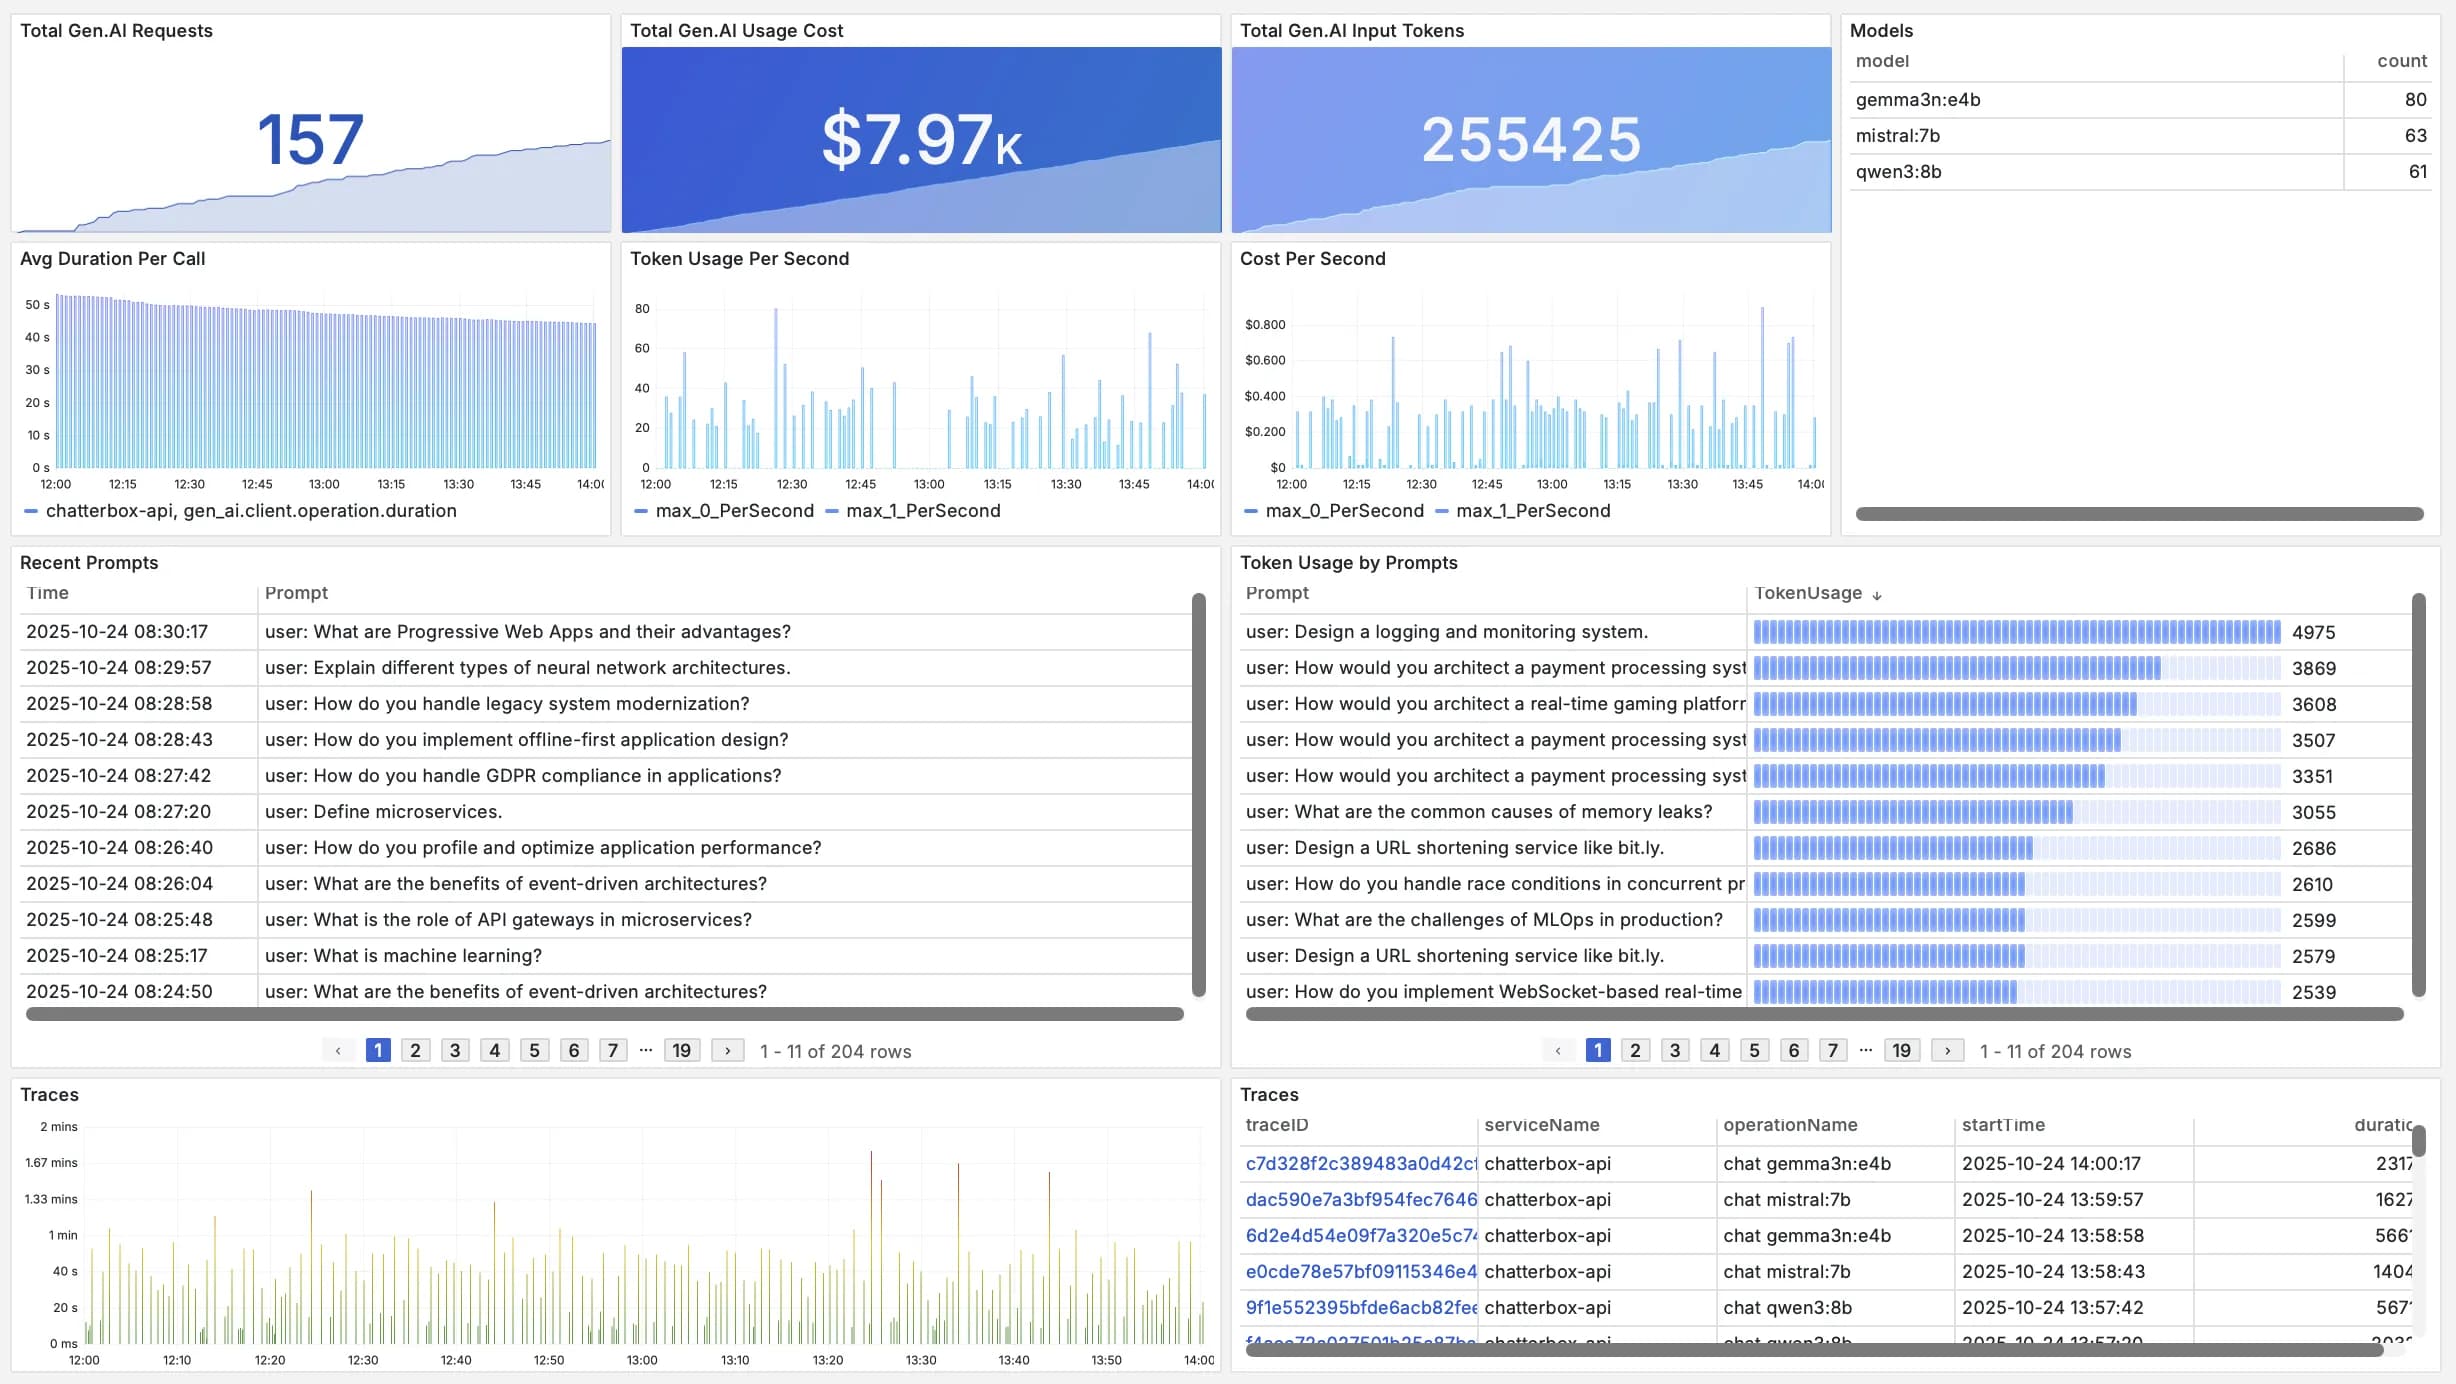
Input and output tokens on every model call, rolled up by model, agent, tool or any attribute you add. Cost is estimated from a price table you control, so local models and new providers are never a blind spot.
- Token usage by model
- Cost by agent
- Cost spike alerts
Catch the failures a successful run hides: tool calls that errored and recovered, retries, fallbacks and nested agent errors, grouped by error type.
- Error type grouping
- Retry and fallback counters
- Human-wait durations
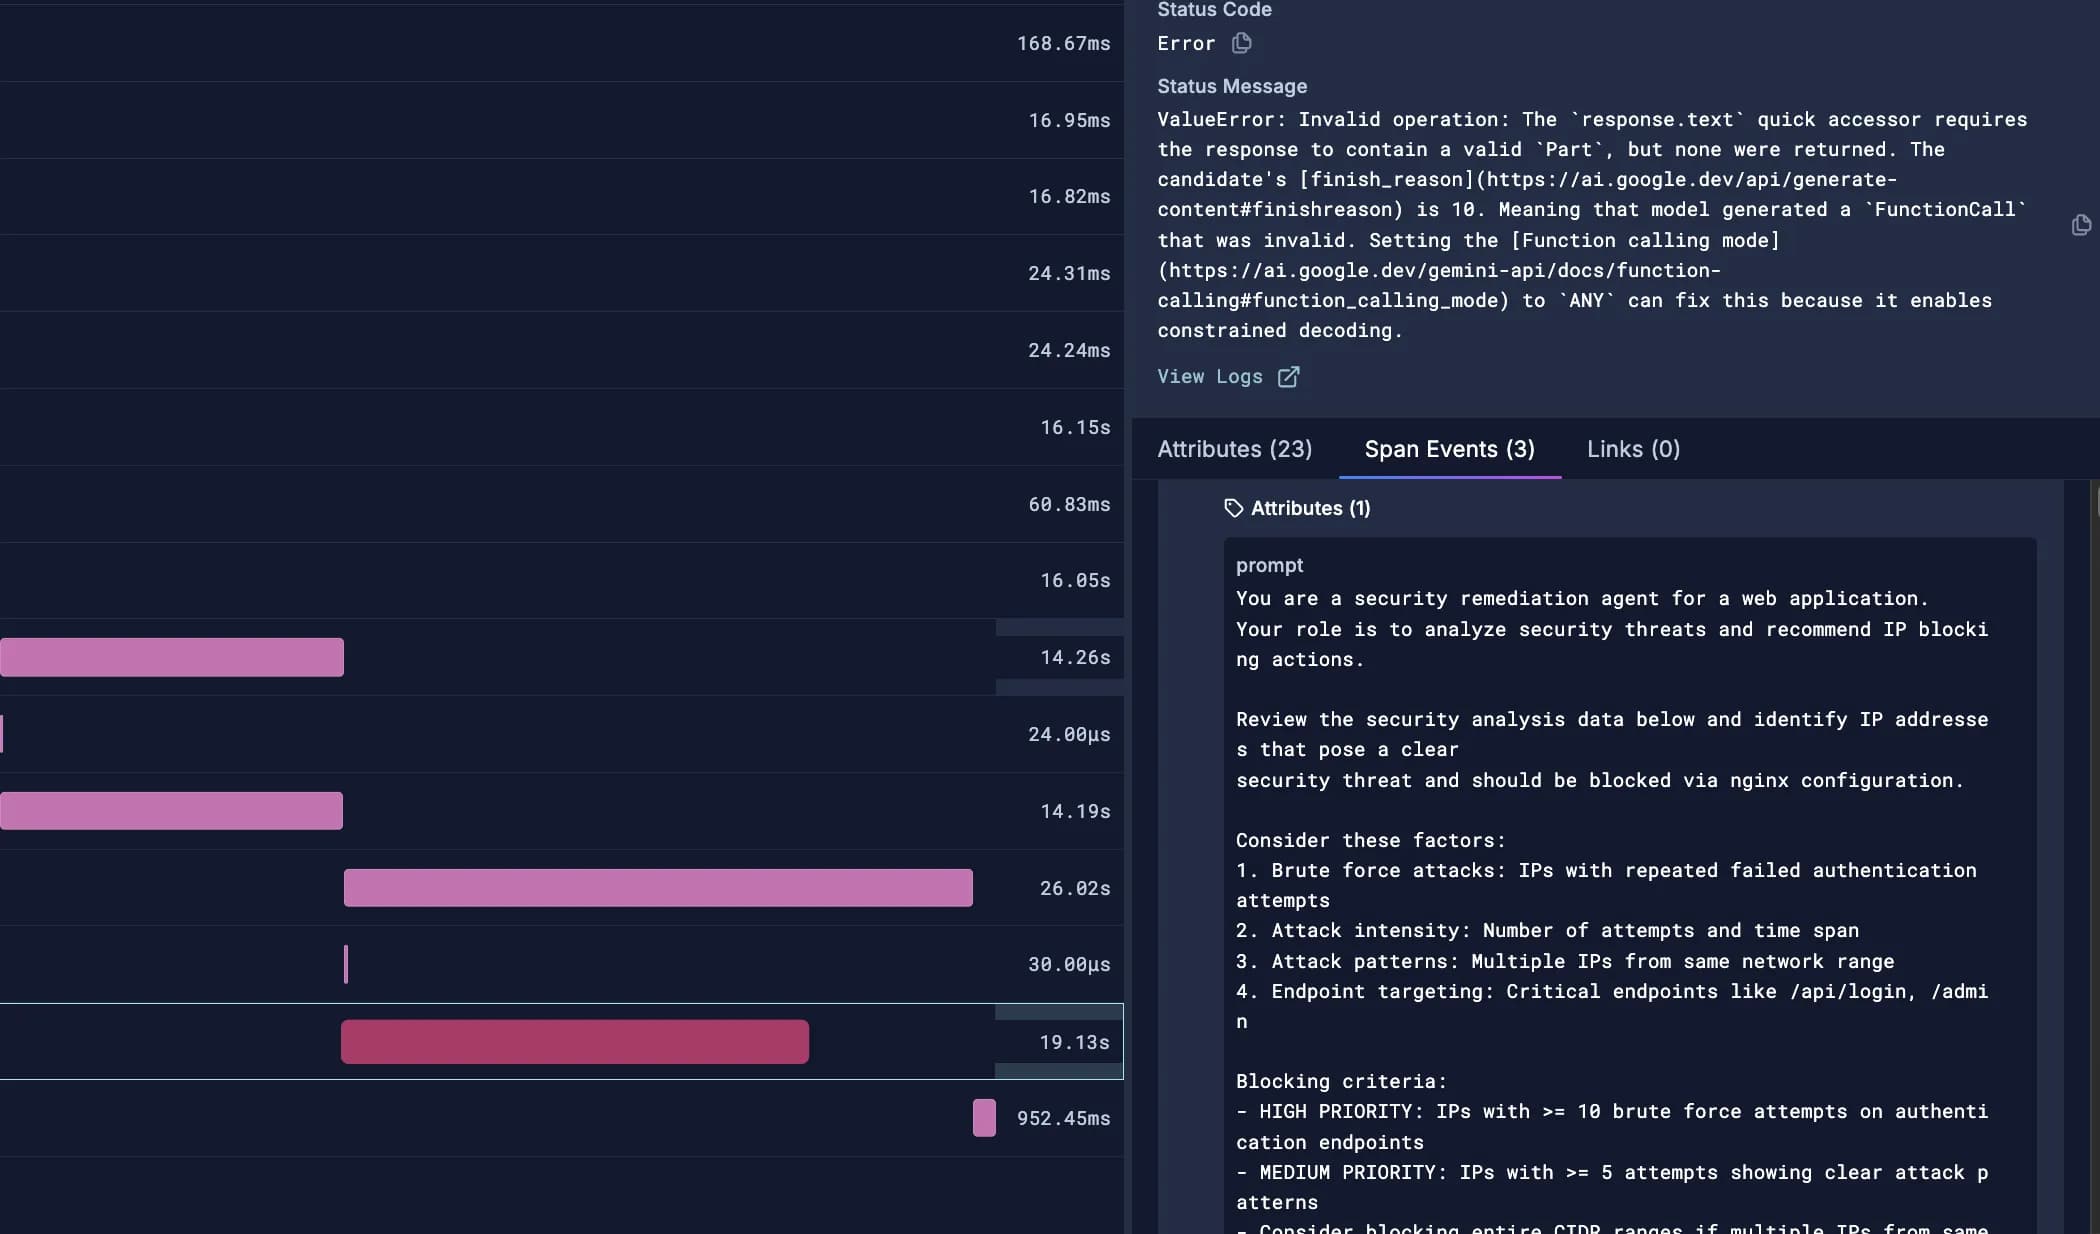
Prompts and completions stay off by default. Turn them on per span or event, scrub PII before export, and attach evaluation scores to the spans they judged.
- Evaluation events and scores
- PII scrubbing
- Version prompts with Scope
Correlate with every other signal
Agent and model spans sit in the same trace as your services, so you never leave Scout to find the cause.
Built on OpenTelemetry's GenAI conventions
No proprietary SDK. Instrument once with OpenTelemetry and send to Scout or any other OTLP backend.
OpenTelemetry GenAI
The official GenAI instrumentation packages for OpenAI, Anthropic and Google, plus the semantic conventions for agents, tools and MCP, with versions pinned and documented.
Your framework's telemetry
Step-by-step guides for LangGraph, LangChain, LlamaIndex, Pydantic AI, Strands Agents, Google ADK, Microsoft Agent Framework, OpenAI Agents SDK, Vercel AI SDK and Mastra.
Coding agents too
Collect telemetry from Claude Code, Codex CLI and OpenClaw, and from LiteLLM and vLLM, into the same workspace.
Trusted worldwide
Notes from the field
“Our goal was to improve reliability without increasing cost, and base14 made that possible. The ability to view APM, infra, and database insights together has helped our team move from reactive to data-driven problem solving. It's an observability platform that actually makes engineers faster and executives more confident.”
Sahil Kharb
Founder, Glomo
AI observability FAQs
Common questions about tracing LLM apps and agents with Scout